Program your memory
Schemas are the programming language for memory. Define what to extract, what to exclude, and how records relate and update. xmemory applies that specification to memory operations.
Define what gets extracted, stored, and updated using schemas as your programming language. Written by developers or agents, executed by xmemory, and evolved alongside your workflows.
Start with a customer's current subscription. When your workflow needs scheduled upgrades,
extend the schema and test the new extraction rules.
01 / Current subscriptions
XMD field excerpt
current_plan:
  type: str
  description: >-
    The customer's active plan.
    Exclude scheduled changes.
For “Acme is on Basic and upgrades to Pro on 1 October 2026,” the current plan is Basic.
02 / Add scheduled upgrades
Keep current_plan; add these XMD fields
scheduled_plan:
  type: str
  description: >-
    A confirmed future plan change.
    Exclude hypothetical upgrades.
effective_on:
  type: str
  description: >-
    Scheduled change date, YYYY-MM-DD.
The same input should now also extract scheduled_plan: Pro and effective_on: 2026-10-01.
Define the memory your agents need, from recurring project tasks to shared team workflows.

Define the plans, task states, research findings, and tool knowledge your agents share. Evolve that memory model as your workflows grow and change.

Connect xmemory to Claude Code, Codex, the Claude app, or ChatGPT. Build structured memory for recurring tasks and ongoing projects, and share it across your team so agents can reuse knowledge across tools and sessions.

Make memory rules explicit and operations reviewable. Inspect stored records, trace reads and writes, and test schema changes before applying them to your workflow.
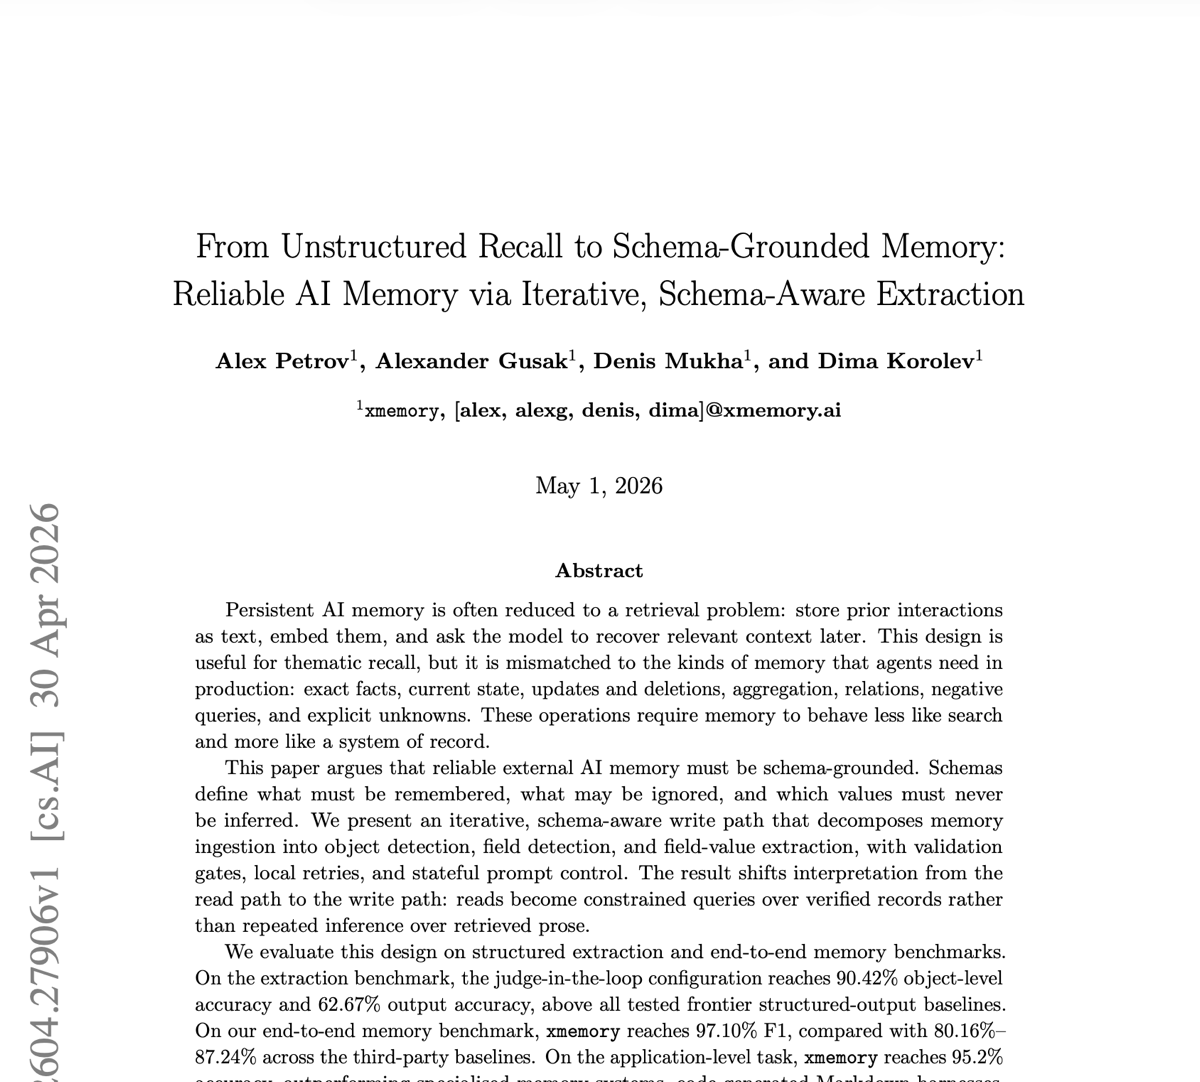
We evaluate whether systems can store, update, deduplicate, and retrieve facts and relationships reliably, not just whether they can recall similar text.*
* Read more about measurement methodology and open benchmarks in our white paper.
Lower token use than text-based memory by optimising reads.
2x+ fewer tokens
Assuming 10 reads per write,
10 write tokens per 5 read tokens for xmemory,
and 5 write tokens per 12 read tokens for typical text-based storage architecture.
Please install xmemory using this prompt
xmemory and Temporal are partnering to bring reliable execution and shared, structured state to developers building long running agents.
What the FLT formalization and Prove2Me teach us about retrieval, accepted state, and programmable agent memory.
What two frontier-agent projects reveal about the shift from transient context to explicit, typed, and verified state.
Schema is the programming language for memory - easy to create, and kept perfectly fit by a schema evolution engine.
Why benchmark leadership can be misleading for AI memory, and what reliability metrics should measure instead.
As business logic moves into prompts, the boundary between agent reasoning and system-owned semantics needs to become much cleaner.
The core idea behind xmemory and why text-only memory misses many complex memory request types.
Your XMD schema defines the objects, fields, allowed values, identity keys, and relationships in memory. Its descriptions instruct extraction: what qualifies, what to exclude, how to interpret evidence, and how to normalise values. Developers or agents can author those rules, inspect stored records, and test extraction before persisting inputs. See the XMD guide for the programming language and examples.
Maintain your schema alongside your workflow code. Developers and agents can revise extraction instructions, add fields or relationships, and test the new behaviour against representative inputs. Validate the revised schema and review a migration dry run before applying changes to existing memory. xmemory also provides tools to suggest schema improvements. Read about schema evolution and the validation and migration workflow.
You define the memory model and extraction rules in schemas that developers and agents can write, test, and evolve. xmemory executes that specification through the pipeline that turns natural-language agent input into structured, validated records:
MCP exposes database tools; you still need to implement the extraction and memory update pipeline. With xmemory, you maintain the schema that governs memory behaviour, while the engine runs that pipeline. For the deeper architectural argument, seeShould Agents Adapt to Systems - or Should Systems Adapt to Agents?.
You can write the schema yourself, have your agent author it, or generate a starting point from a workflow description. Every path gives you an explicit specification to inspect and test:
SeeHow xmemory works for the full flow, then use the XMD guide when you want to review or improve extraction.
Text and vector memory can retrieve relevant context. Schemas let you also specify what qualifies as a fact, how it is represented, and how records relate and update. xmemory uses those instructions to extract and validate structured records that you can inspect and query. Natural-language instructions still guide extraction; the memory specification is explicit, testable, and maintained alongside your workflow. For the fuller argument, readSchema as the Core of Reliability in AI Memory.
xmemory is external storage that agents use like a database or file store to save and retrieve context. Agents can create memory instances themselves, define schemas for a task on the fly, or use fixed instances for longer-lived context. It can reliably replace an agentic system of record, or run as a sidecar validation engine with periodic sync to the system of record, so people can review updates before they merge. The simple rule is: whenever agents need to save and retrieve text information, that layer can be xmemory. You can jump straight to theintegration guidesinHow xmemory works.
Tell us what your agents need to remember and how that memory should behave. We’ll help you define the schema and connect xmemory to your workflow.
© 2026 xmemory Inc. All rights reserved.